Effect Size
Study these flashcardsFree · spaced repetition · iPhone, Android, Mac & web
All cards
1
Define effect size
Difference in means between 2 populations
2
Which error is of main concern to scientists? And why?
Type 1 errors
Trying to reduce this
Misconception that only positive results matter so failure to reject null (type 2 error) not considered interesting/important
Trying to reduce this
Misconception that only positive results matter so failure to reject null (type 2 error) not considered interesting/important
3
Why are large effect sizes needed?
To detect type 1 errors
To detect the difference between H0 and H1
To detect the difference between H0 and H1
4
What increases the probability of getting a type 1 error?
High numbers of comparisons (the multiple comparisons problem)
5
What is used to correct the multiple comparisons problem?
Bonferroni correction
Adjusts alpha by the number of comparisons (K)
alpha over k
Adjusts alpha by the number of comparisons (K)
alpha over k
6
What increases the likelihood of type 2 errors?
Applying more stringent tests
Reduces likelihood of type 1 but increase likelihood of type 2 as they are inversely related
Reduces likelihood of type 1 but increase likelihood of type 2 as they are inversely related
7
Criticisms of null hypothesis significance testing
- Encourages dichotomous thinking
- p < alpha doesn't necessarily indicate scientific progress
- Need a more meaningful way of asking how big/strong is the effect / relationship?
- p < alpha doesn't necessarily indicate scientific progress
- Need a more meaningful way of asking how big/strong is the effect / relationship?
8
Define power
Ability to detect a real difference
1-beta
1-beta
9
What happens to the spread of data when enough samples are included?
Sample means will cluster around the population mean
10
Evaluate effect size
+ Useful for detecting size of effects in the real world
- Standardisation problem
- Standardisation problem
11
Purpose of Cohen's d
Provides a standardised index of effect size
Allows for comparison of effect size across different studies
Forms the basis of meta-analyses
Allows for comparison of effect size across different studies
Forms the basis of meta-analyses
12
What is considered a large effect for Cohen's d?
> or equal to 0.8
13
What does Cohen's d depend on?
Whether data is paired (repeated measures) or unpaired (independent groups/matched pairs)
14
For Cohen's d what is better: paired or unpaired samples?
Paired > unpaired
Reduces sample variance and increases the power
Reduces sample variance and increases the power
15
How to calculate standard deviation of difference table in a calculator
Menu
2
1-variable
Input data
AC
OPTN
1-variable Calc
sx = standard deviation value
2
1-variable
Input data
AC
OPTN
1-variable Calc
sx = standard deviation value
16
What do small effect sizes require?
Larger samples in order to reject H0
17
What is the threshold for power?
0.8
Anything less than this increases the likelihood of type 2 errors
Anything less than this increases the likelihood of type 2 errors
18
What happens as sample size increases?
Variance of sample distribution decreases (less overlap)
Increases power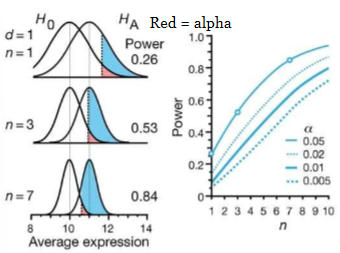
Increases power
19
What happens as effect size increases?
Separation between distributions increases
Increases power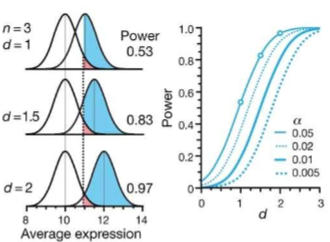
Increases power
20
Define confidence interval
Gives esimated range of values likely to include the unkown population mean
21
What is one of the limitations of all sampling techniques?
Estimation error
22
What do you do if the sample mean is in the shaded regions?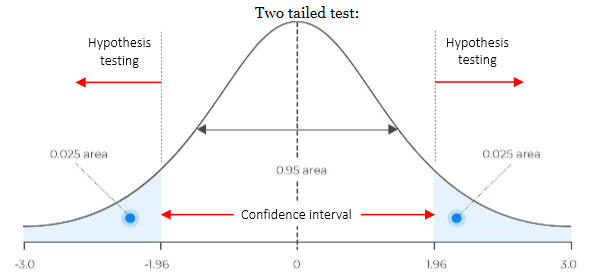
Reject the null
Accept H1
Accept H1
23
Larger confidence intervals _____ likely to include population mean
- less
- just as
- more
24
3 factors that increase the width of the confidence interval
Increasing the confidence level
Reducing the sample size
Increasing the variability of the sample data (eg. more outliers)
Reducing the sample size
Increasing the variability of the sample data (eg. more outliers)
25
When is standard deviation used?
Raw data
Often population level
Often population level
26
When is standard error used?
When talking about samples
27
What can you conclude from overlapping confidence intervals?
Zone of uncertainty
Don't know which distribution a value in this area belongs to
Need to use variance sum law??
Don't know which distribution a value in this area belongs to
Need to use variance sum law??
28
What is used to measure effect size?
R2
29
Define the total sum of sqaures
Sum of squared differences b/w the mean and the observed data
30
Define the residual sum of squares
Sum of squared difference b/w the regressio line and the observed data
Total error in the model using the mean value
Total error in the model using the mean value
31
Define the model sum of squares
Represents improvement in predictions using the regression line over the mean
32
What is the model sum of squares used for?
To decide whether a statistical model is a good fit for the data
33
How to calculate the model sum of squares
SSm = SSt - SSr
34
How to calculate R2
SSm / SSt
35
How to know which effect size measure to use?
Effect size measure of 2 in/dependent groups = Cohen's d
Correlational measure of effect size = r and R2
Correlational measure of effect size = r and R2
36
Why might effect size and meta analyses be used together?
Used to integrate data from may independent replication studies
Provides more robust conclusion about direction and size of an effect
Visualised using a forest plot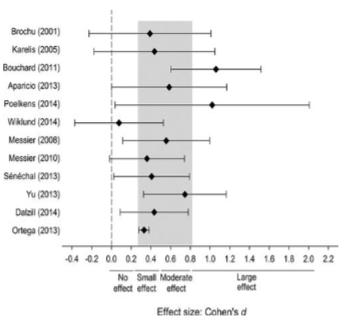
Provides more robust conclusion about direction and size of an effect
Visualised using a forest plot
37
Limitations of using small samples
Reduced effect size - effect no longer visible
Very low power
To reject null, mean has to be in extremes - can be possible in small samples by chance
Very low power
To reject null, mean has to be in extremes - can be possible in small samples by chance
38
What 2 things does statistical power depend strongly on?
Effect size
n
n